

Velvet2-3B Speech
October 29, 2026
A multilingual speech-language model designed to understand spoken content beyond words, capturing the rich information conveyed through speech to perform complex language tasks directly from audio.
The essence of Velvet2-3B Speech
Velvet2-3B-Speech builds on the Velvet2 language foundation model by integrating speech processing, creating a versatile model for applications where voice is a natural source of information.
Languages
English, Italian, Spanish Portuguese, French, German
Architecture
The architecture combines the Velvet2-3B language model, a Whisper Large v3 audio encoder and a dedicated projector connecting acoustic and language representations.
Training Dataset
Nearly 30 million audio examples across six languages, totaling approximately 95,000 hours of speech and combining open datasets with synthetic data.
Context Window
32K tokens. The maximum supported audio duration is about 22 minutes.
Responsible AI
Safety measures integrated across data curation, training and post-training, including data filtering, quality controls, alignment and safety evaluation, supported by continuous internal governance and oversight.
Parameters
3B language model + 0.7B audio encoder.
Data Freshness
Pretraining data cutoff: December 2025 – January 2026.
License
Open weight with Apache 2.0 license.
Capabilities
Automatic Speech Recognition
Information Extraction
Speech Translation
Speech Emotion Recognition
Function
Calling From Speech
Language
Identification
Instruction Following
Question Answering From Speech
Multiturn Conversation
Structured Output Generation
Summarization From Speech
Performance Evaluation
Velvet2-3B-Speech was evaluated across a range of benchmarks covering speech recognition, spoken language understanding, translation and emotion recognition.
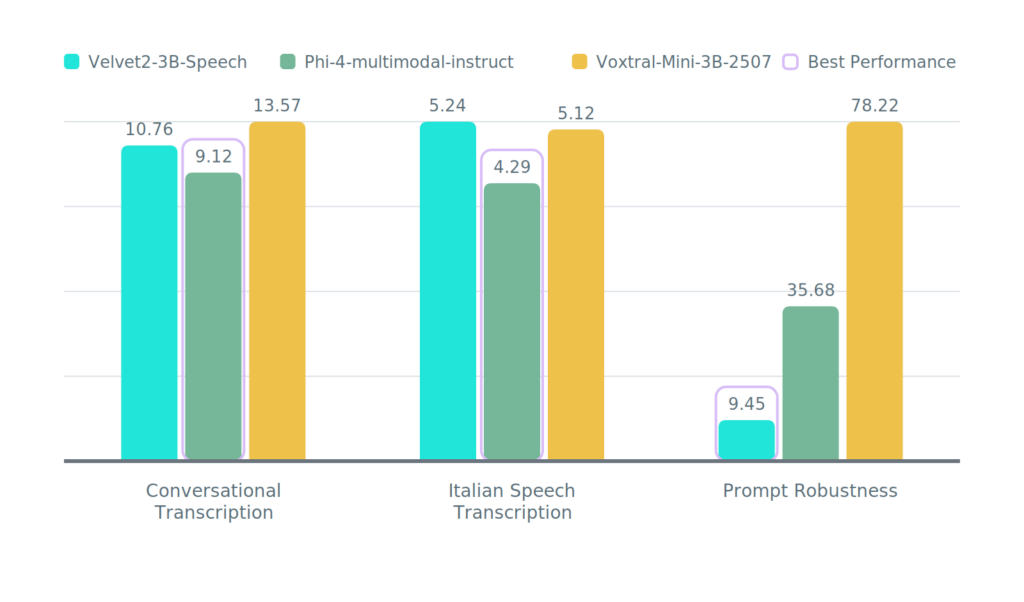
Transcription & Robustness
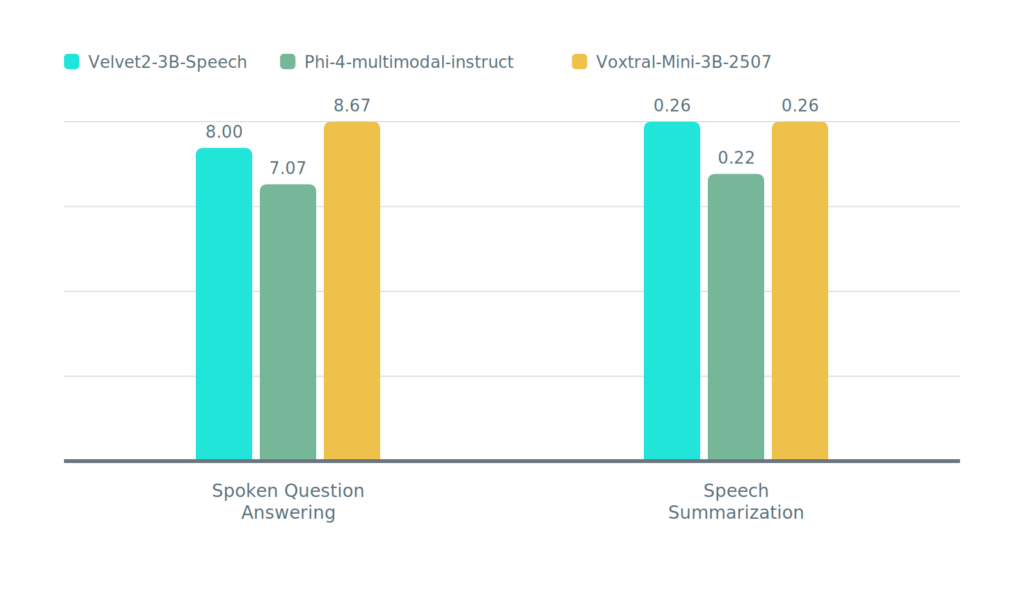
Speech Understanding
Metrics
Conversational Transcription (AMI)
Measures transcription accuracy in real conversations and meetings.
Example prompt: “Transcribe this conversation accurately.”
Italian Speech Transcription (Multilingual ASR Italian)
Measures transcription accuracy for spoken Italian.
Example prompt: “Transcribe this Italian audio.”
Prompt Robustness (DOWIS)
Measures transcription consistency across differently worded instructions.
Example prompt: “Write down exactly what is being said.”
Spoken Question Answering (HeySquad EN)
Measures how well spoken questions are understood and answered.
Example prompt: “Listen to the question and give me the answer.”
Speech Summarization (VoxPopuli-L EN)
Measures how well long spoken content is summarized.
Example prompt: “Summarize the main points of this recording.”
Discover Velvet AI Models
Velvet Speech-2B
Velvet-2B-1.5
Velvet-2B
Velvet-14B
Velvet-25B
Velvet2-3B text
Velvet2-3B vision
Why Velvet2-3B Speech?
Audio and Multimedia Content
Turn spoken content into information that can be analyzed, summarized and queried, while capturing additional signals such as emotion to support richer processing of large audio and multimedia collections.
Multilingual Voice Content
Build applications that need to handle voice interactions in multilingual environments, where speakers may naturally switch between languages within the same conversation.
Language Tasks from Speech
Use voice as the starting point for tasks such as answering questions, generating summaries or triggering functions, rather than stopping at transcription.