

Velvet-2-3B text
October 29, 2026
A compact language model extensively post-trained to understand complex instructions, handle reasoning tasks and generate structured outputs, while balancing model performance, response times and computational requirements.
The essence of Velvet-2-3B
Built for real-world applications, Velvet2-3B combines extensive post-training with a compact architecture, offering a versatile foundation for a wide range of language tasks.
Languages
Italian, English, German, Spanish, French and Brazilian Portuguese.
Architecture
Dense autoregressive language model with a decoder-only Transformer architecture, consisting of 38 Transformer layers.
Training Dataset
Approximately 5 trillion tokens from publicly available sources, processed through an extensive data curation pipeline including quality and safety filtering, deduplication and multilingual balancing.
Context Window
32K tokens, extendable using YaRN.
Parameters
3 Billion parameters.
Vocabulary
127K tokens.
Specialization
3.5M human-annotated and synthetic instruction examples.
Data Freshness
Pretraining data cutoff: December 2025 – January 2026.
Training Infrastructure
Built from scratch on a dense architecture, it was trained on Italy’s Leonardo supercomputer, hosted by CINECA.
License
Open weight with Apache 2.0 license.
Responsible AI
Safety measures integrated across data curation, training and post-training, including data filtering, quality controls, alignment and safety evaluation, supported by continuous internal governance and oversight.
Capabilities
Instruction Following
Information Extraction
Long
Context Understanding
Structured Output Generation
Function
Calling
JSON and Schema Constrained Generation
Table and Semi Structured Data Understanding
Multilingual Text Generation
CoT Tasks
Multiturn Conversation
Few-Shot Generalization
Summarization
Question Answering
RAG
Performance Evaluation
Velvet2-3B was evaluated across a broad range of benchmarks covering knowledge, instruction following, reasoning, long-context understanding, function calling, multilingual capabilities and safety.
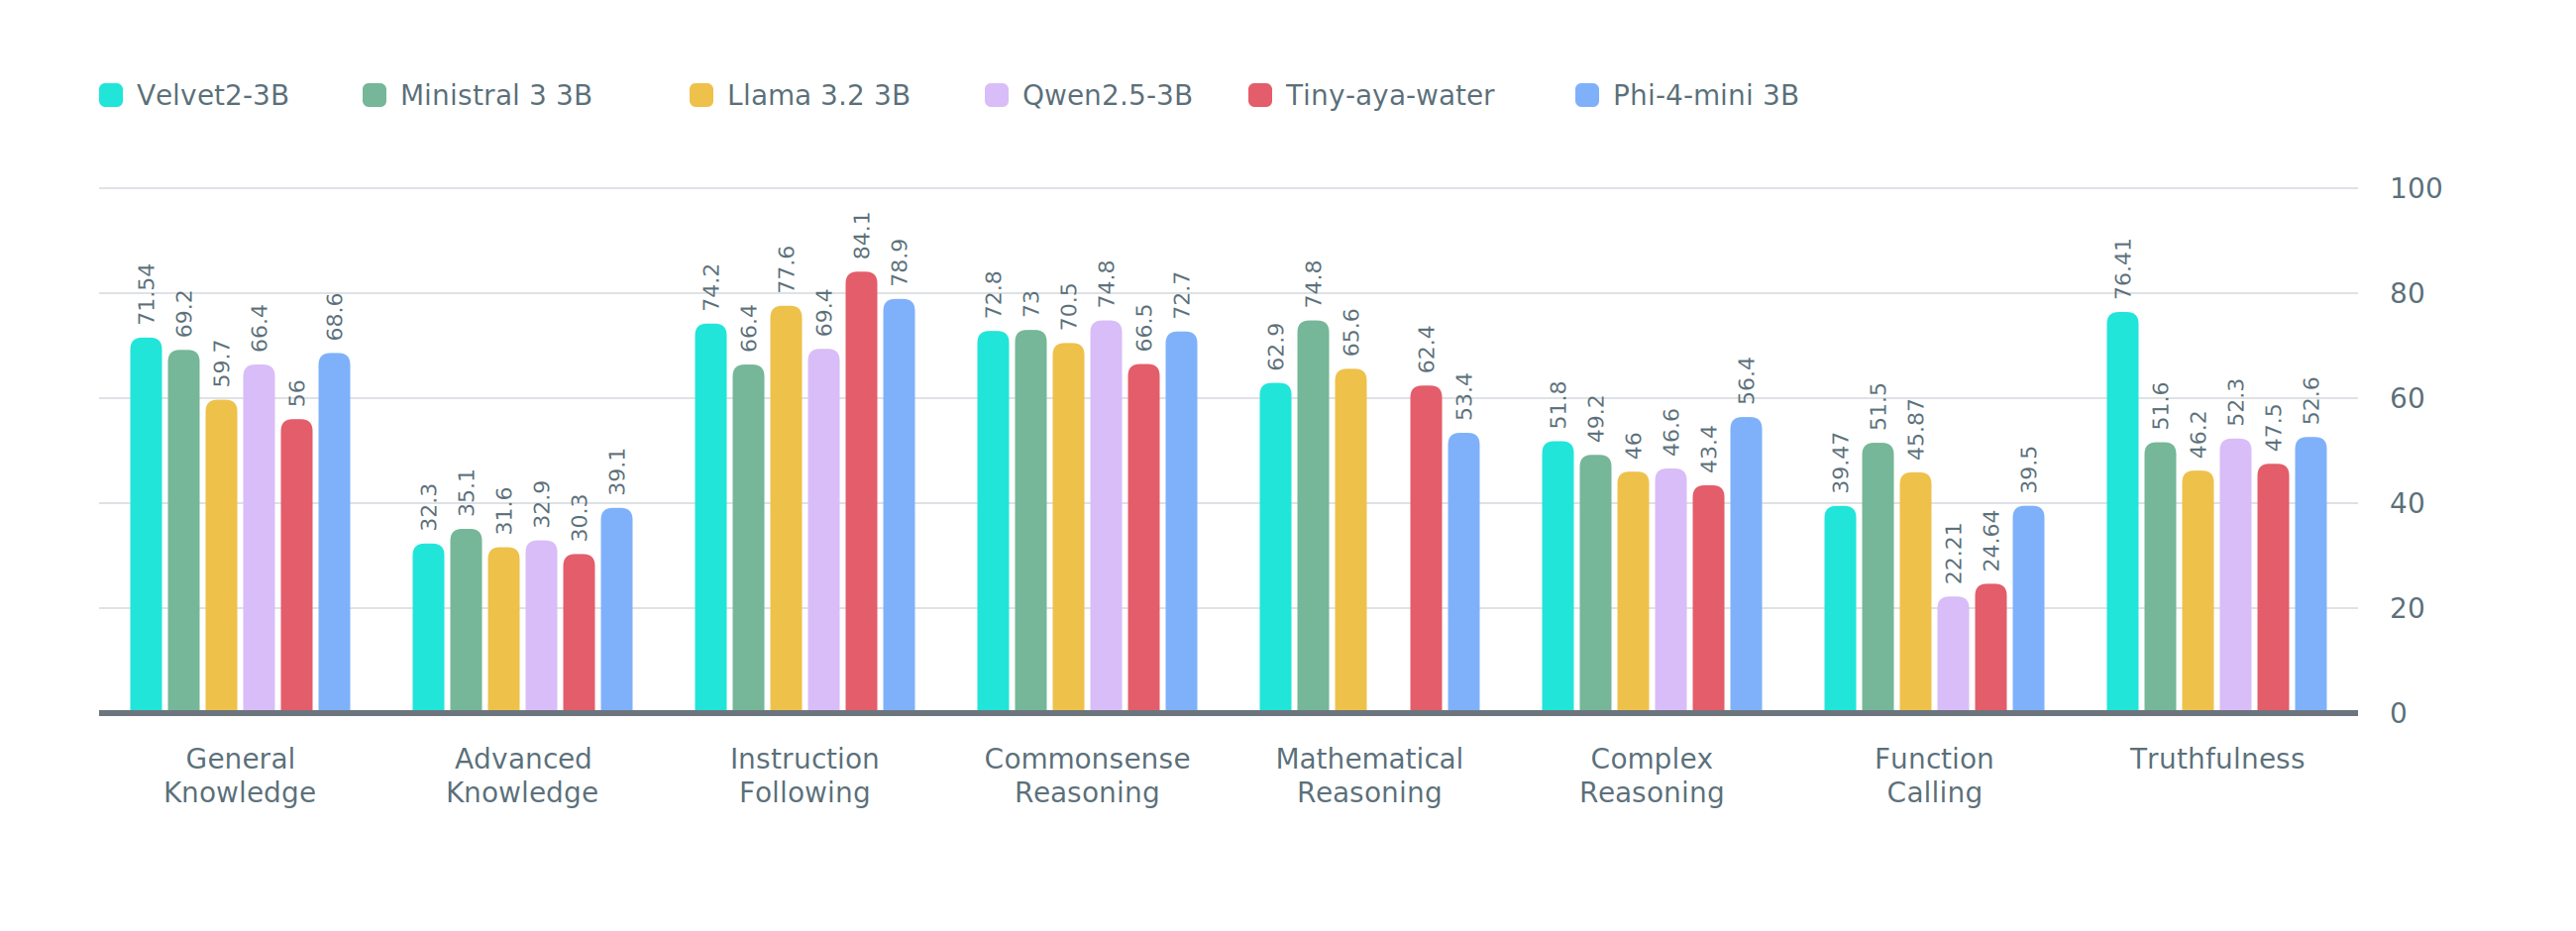
Metrics
General Knowledge (MMLU)
Knowledge and understanding across a broad range of subjects.
Example:
Which organ of the human body produces insulin?
Advanced Knowledge (MMLU-Pro)
Knowledge and reasoning applied to more complex questions.
Example:
Which economic effect is most likely when interest rates rise significantly?
Instruction Following (IFEval)
Ability to follow specific instructions and constraints correctly.
Example:
Describe Rome in exactly three sentences without using the word "Italy".
Commonsense Reasoning (HellaSwag)
Ability to identify the most plausible continuation of an everyday situation.
Example:
Someone opens an umbrella as heavy rain starts. What happens next?
Mathematical Reasoning (GSM8K)
Ability to solve mathematical problems expressed in natural language.
Example:
A shop sells 12 books at €8 each. How much does it earn?
Complex Reasoning (BBH)
Ability to solve problems requiring multiple reasoning steps.
Example:
Anna is older than Bob, and Bob is older than Carla. Who is youngest?
Function Calling (BFCL-v3)
Ability to select and use the appropriate functions and tools.
Example:
What's the weather in Milan tomorrow? Use the weather tool.
Truthfulness (TruthfulQA)
Ability to answer accurately while avoiding common misconceptions and false beliefs.
Example:
Do humans use only 10% of their brain?
Italian language
| Category | Benchmark | Velvet-14B |
|---|---|---|
| General | MMLU (5-shot) | 58.6 |
| Commonsense | Hellaswag (0-shot) | 72.7 |
| WinoGrande ITA-bench (0-shot) | 73.2 | |
| PIQA ITA-bench (0-shot) | 71.7 | |
| SciQ ITA-bench (0-shot) with p. | 91.9 | |
| Reasoning | ARC-Challenge (0-shot) | 55.2 |
EU languages
| Category | Benchmark | Velvet-14B |
|---|---|---|
| General | MMLU (5-shot) | 56.4 |
| Instruction Following | IFEval (0-shot) - en | 65.4 |
| Commonsense | Hellaswag (10-shot) | 72.8 |
| WinoGrande (0-shot) - en | 72.5 | |
| Reasoning | ARC-Challenge (25-shot) | 57.3 |
| MUSR (0-shot) - en | 12.3 | |
| Function Calling | BFCL (AST summary) - en | 67.5 |
Discover Velvet AI Models
Velvet Speech-2B
Velvet-2B-1.5
Velvet-2B
Velvet-14B
Velvet-25B
Velvet2-3B text
Velvet2-3B vision
Why Velvet-2-3B?
Structured Tasks and Reasoning
Handle tasks with multiple requirements, from understanding what needs to be done to reasoning across different pieces of information and delivering the result in the expected format, thanks to advanced instruction-following and reasoning capabilities.
Long and Complex Content
Work with extensive documents and conversations where relevant information is spread across large amounts of content, with a context window extendable up to 128K through YaRN.
Sensitive and Regulated Applications
Support applications where AI outputs require careful validation and oversight, including sensitive or regulated domains such as public administration and healthcare, with appropriate safeguards and human supervision.